Vietnam GPU Server Rental Price List
Price list for 1 month and 12 months is reduced by 15%, including popular GPU configurations for AI, rendering, model training and workloads that require graphics processing power.
2 × GPU24 GB per GPU
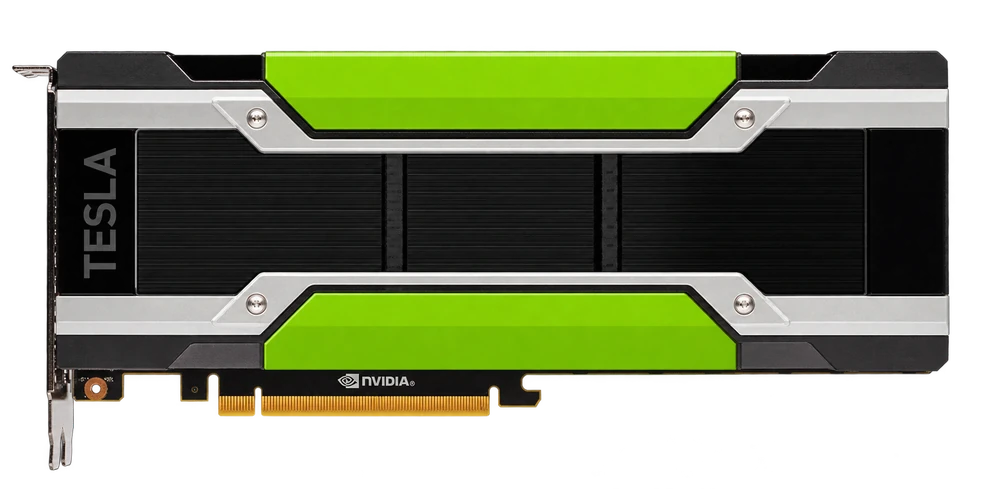
GPU-2 x P40
Private server with 2 Nvidia Tesla P40 cards
- CPU
- 2 x Intel Xeon 2667v4
- RAM
- 128 GB
- Storage
- 2TB SSD NVMe
- GPU
- 2 x Nvidia Tesla P40 24G
- CUDA
- 2 x 3840 CUDA Core
- IP
- 01 IPv4
- Support
- 24/7 Support
Save 15% when paying for 12 months Price maintains the service $360 / months - 15% when paying for 12 months
Order now 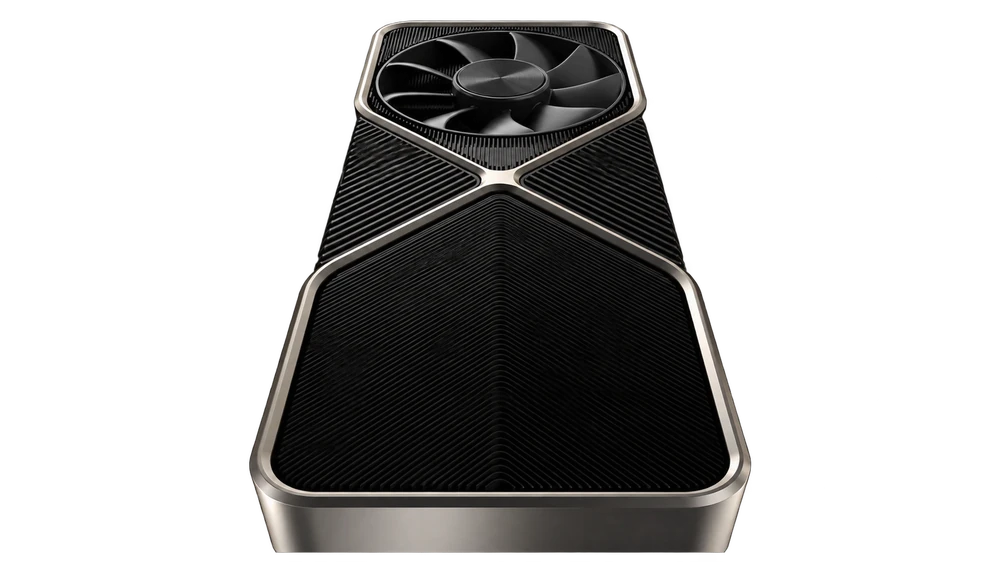
2 × GPU24 GB per GPU
GPU-2 x 3090
Private server with 2 Nvidia RTX 3090 cards
- CPU
- 2 x Intel Xeon 2667v4
- RAM
- 128 GB
- Storage
- 2TB SSD NVMe
- GPU
- 2 x Nvidia RTX 3090 24G
- CUDA
- 2 x 10496 CUDA Core
- IP
- 01 IPv4
- Support
- 24/7 Support
Most popular Price maintains the service $800 / months - 15% when paying for 12 months
Order now 4 × GPU24 GB per GPU
GPU-4 x 3090
Enjoy dedicated performance & resource optimization
- CPU
- 2 x Intel Xeon 2667v4
- RAM
- 128 GB
- Storage
- 2TB SSD NVMe
- GPU
- 4 x Nvidia RTX 3090 24G
- CUDA
- 4 x 10496 CUDA Core
- IP
- 01 IPv4
- Support
- 24/7 Support
Save 15% when paying for 12 months Price maintains the service $1,400 / months - 15% when paying for 12 months
Order now 8 × GPU24 GB per GPU
GPU-8x3090
Private server with 8 Nvidia RTX3090 cards
- CPU
- 2 x Intel Xeon Gold 6133
- RAM
- 256 GB
- Storage
- 4TB SSD NVMe
- GPU
- 8 x Nvidia RTX 3090 24GB
- CUDA
- 8 x 10496 CUDA Core
- IP
- 01 IPv4
- Support
- Contact Support to order
Save 15% when paying for 12 months Price maintains the service $2,400 / months - 15% when paying for 12 months
Order now 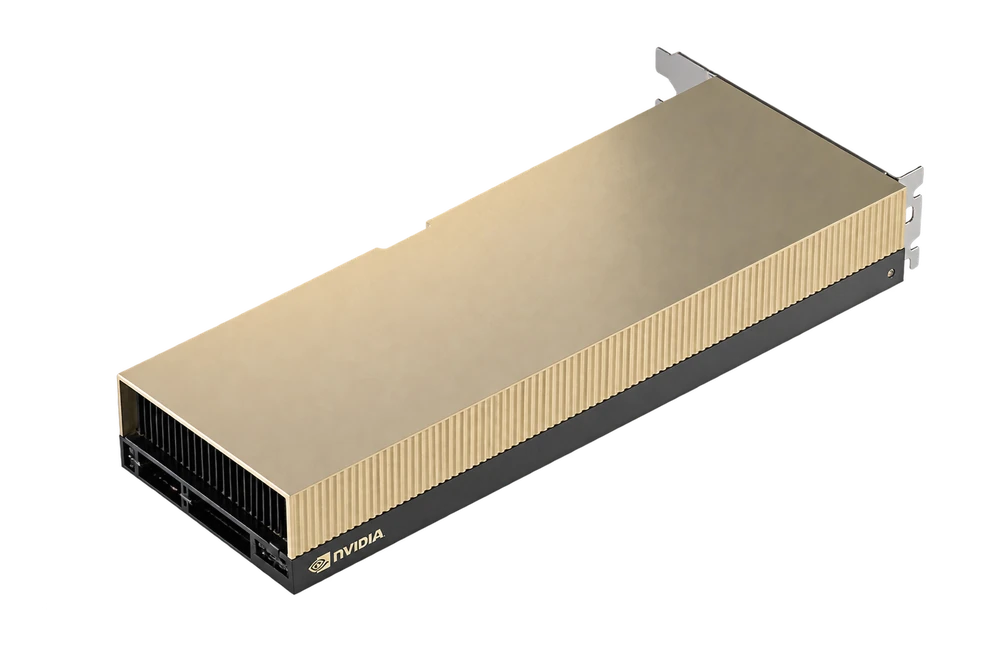
1 × GPU24 GB per GPU
GPU-A30
Private server with 1 Nvidia A30 card
- CPU
- 2 x Intel Xeon Gold 6133
- RAM
- 128 GB
- Storage
- 2TB SSD NVMe
- GPU
- Nvidia A30 24GB
- Human processing
- Tensor Core GPU
- IP
- 01 IPv4
- Support
- Contact Support to order
Save 15% when paying for 12 months Price maintains the service $1,000 / months - 15% when paying for 12 months
Order now 2 × GPU24 GB per GPU
GPU-2xA30
New generation powerful Tensor Core server
- CPU
- 2 x Intel Xeon Gold 6133
- RAM
- 256 GB
- Storage
- 4TB SSD NVMe
- GPU
- 2 x Nvidia A30 24GB
- Human processing
- Tensor Core GPU
- IP
- 01 IPv4
- Support
- Contact Support to order
Save 15% when paying for 12 months Price maintains the service $1,800 / months - 15% when paying for 12 months
Order now 4 × GPU24 GB per GPU
GPU-4 x A30
New generation powerful Tensor Core server
- CPU
- 2 x Intel Xeon Gold 6133
- RAM
- 256 GB
- Storage
- 4TB SSD NVMe
- GPU
- 4 x Nvidia A30 24GB
- Human processing
- Tensor Core GPU
- IP
- 01 IPv4
- Support
- Contact Support to order
Save 15% when paying for 12 months Price maintains the service $3,200 / months - 15% when paying for 12 months
Order now 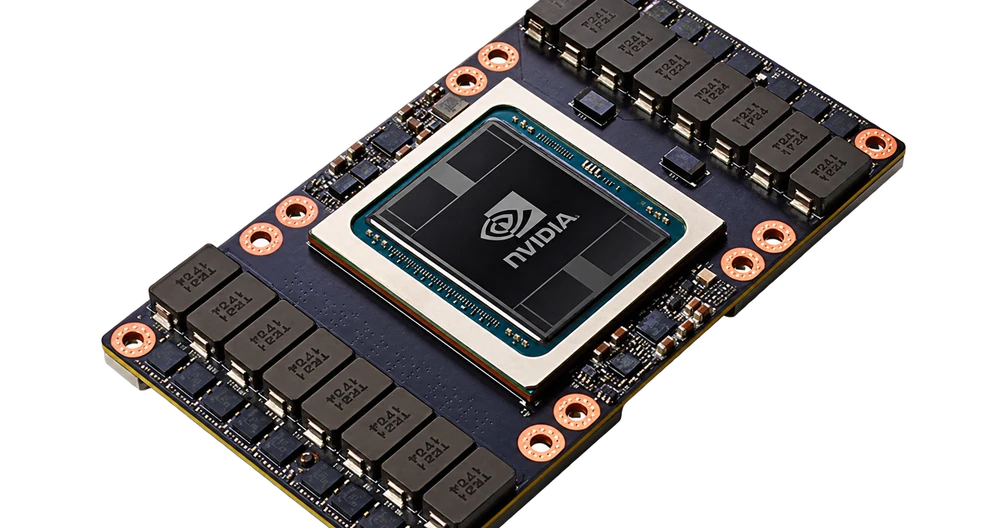
4 × GPU32 GB per GPU
GPU-4 x V100
SXM2 GPU Server - Nvlink Support
- CPU
- 2 x Intel Xeon Gold 6133
- RAM
- 256 GB
- Storage
- 4TB SSD NVMe
- GPU
- 4 x Nvidia Tesla V100 32GB
- Connect
- SXM2 Nvlink AI Server
- IP
- 01 IPv4
- Support
- Contact Support to order
Save 15% when paying for 12 months Price maintains the service $2,000 / months - 15% when paying for 12 months
Order now 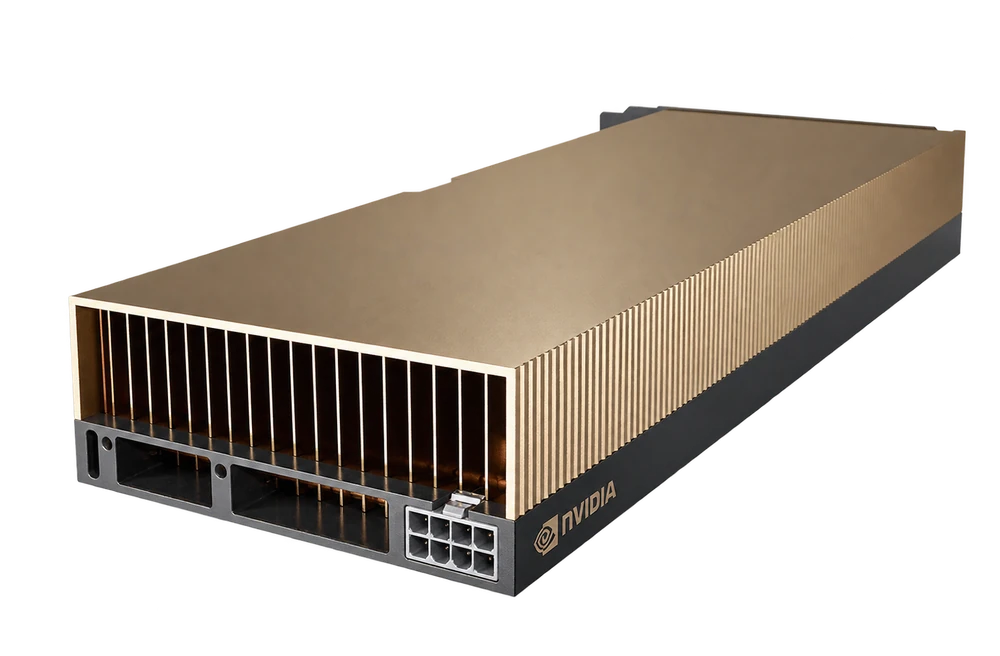
1 × GPU48 GB per GPU
GPU-A40
New generation powerful Tensor Core server
- CPU
- 2 x Intel Xeon Gold 6133
- RAM
- 128 GB
- Storage
- 2TB SSD NVMe
- GPU
- Nvidia A40 48GB
- Human processing
- Tensor Core GPU
- IP
- 01 IPv4
- Support
- Contact Support to order
Save 15% when paying for 12 months Price maintains the service $1,400 / months - 15% when paying for 12 months
Order now 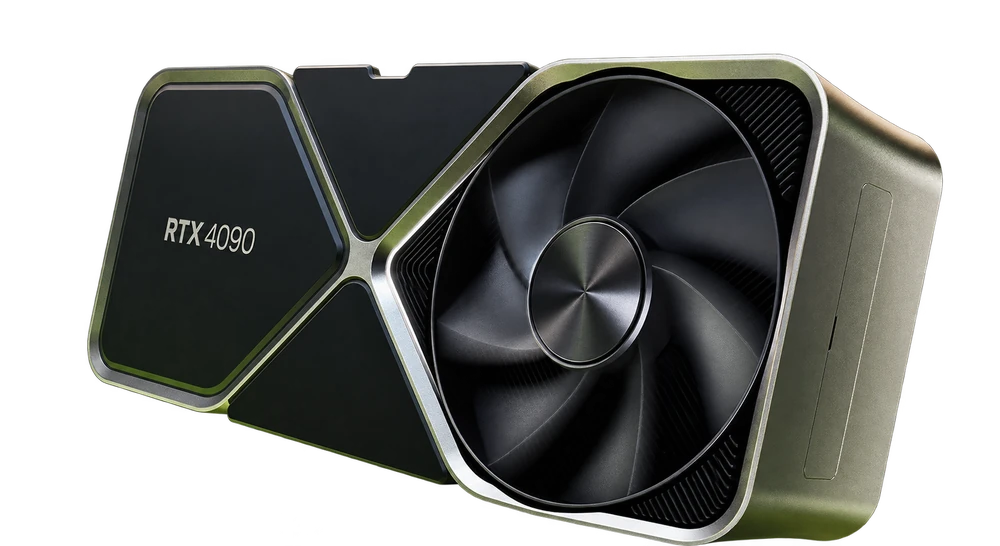
1 × GPU24 GB per GPU
GPU-RTX 4090
New generation powerful Tensor Core server
- CPU
- 2 x Intel Xeon Gold 6133
- RAM
- 128 GB
- Storage
- 2TB SSD NVMe
- GPU
- Nvidia RTX 4090 24GB
- Human processing
- Cuda Core - Tensor Core GPU
- IP
- 01 IPv4
- Support
- Contact Support to order
Save 15% when paying for 12 months Price maintains the service $800 / months - 15% when paying for 12 months
Order now 2 × GPU24 GB per GPU
GPU-2 x 4090
New generation powerful AI server
- CPU
- 2 x Intel Xeon Gold 6133
- RAM
- 256 GB
- Storage
- 4TB SSD NVMe
- GPU
- 2 x Nvidia RTX 4090
- Human processing
- Cuda Core - Tensor Core GPU
- IP
- 01 IPv4
- Support
- Contact Support to order
Save 15% when paying for 12 months Price maintains the service $1,400 / months - 15% when paying for 12 months
Order now 4 × GPU24 GB per GPU
GPU-4 x 4090
New generation powerful Tensor Core server
- CPU
- 2 x Intel Xeon Gold 6133
- RAM
- 256 GB
- Storage
- 4TB SSD NVMe
- GPU
- 4 x Nvidia RTX 4090
- Human processing
- Cuda Core - Tensor Core GPU
- IP
- 01 IPv4
- Support
- Contact Support to order
Save 15% when paying for 12 months Price maintains the service $2,600 / months - 15% when paying for 12 months
Order now 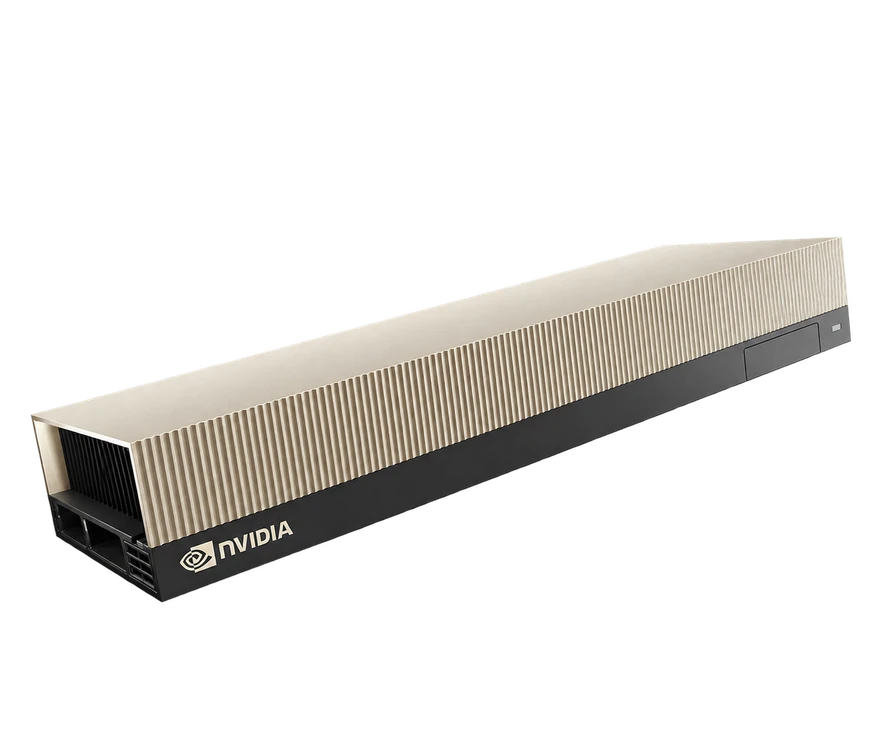
1 × GPU48 GB per GPU
GPU-L40S
New generation server with L40S GPU
- CPU
- 2 x Intel Xeon Gold 6133
- RAM
- 128 GB
- Storage
- 2TB SSD NVMe
- GPU
- Nvidia L40S 48GB
- Human processing
- Cuda Core - Tensor Core GPU
- IP
- 01 IPv4
- Support
- Contact Support to order
Save 15% when paying for 12 months Price maintains the service $1,500 / months - 15% when paying for 12 months
Order now 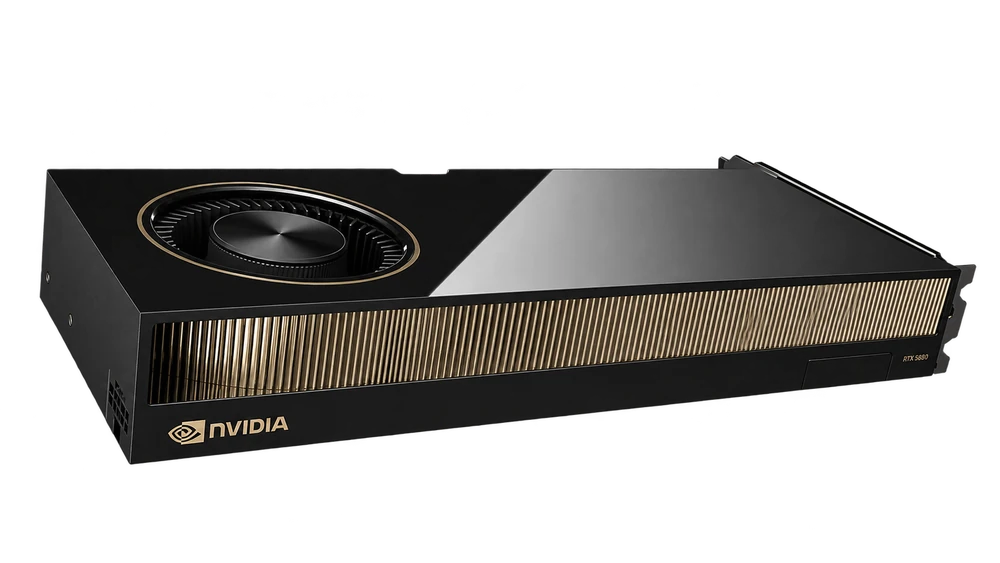
1 × GPU48 GB per GPU
GPU-RTX 5880
New generation powerful AI server
- CPU
- 2 x Intel Xeon Gold 6133
- RAM
- 128 GB
- Storage
- 2TB SSD NVMe
- GPU
- Nvidia RTX 5880 ADA 48GB
- Human processing
- Cuda Core - Tensor Core GPU
- IP
- 01 IPv4
- Support
- Contact Support to order
Save 15% when paying for 12 months Price maintains the service $1,400 / months - 15% when paying for 12 months
Order now 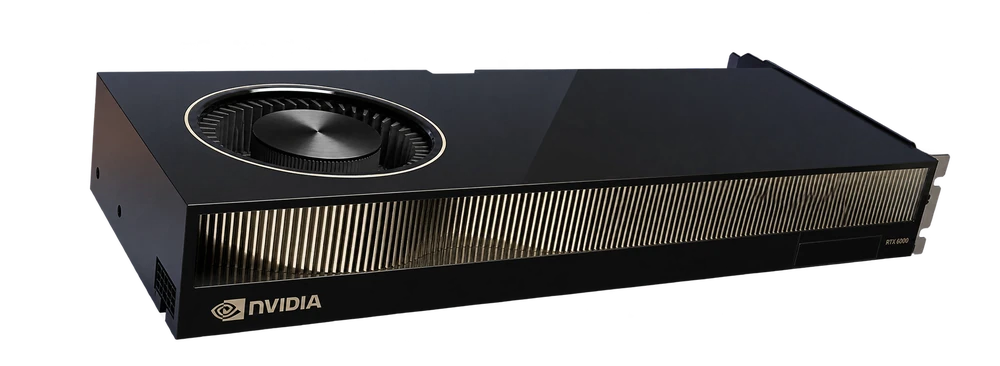
1 × GPU48 GB per GPU
GPU-RTX 6000
New generation powerful Tensor Core server
- CPU
- 2 x Intel Xeon Gold 6133
- RAM
- 128 GB
- Storage
- 2TB SSD NVMe
- GPU
- Nvidia RTX 6000 ADA 48GB
- Human processing
- Cuda Core - Tensor Core GPU
- IP
- 01 IPv4
- Support
- Contact Support to order
Save 15% when paying for 12 months Price maintains the service $1,500 / months - 15% when paying for 12 months
Order now 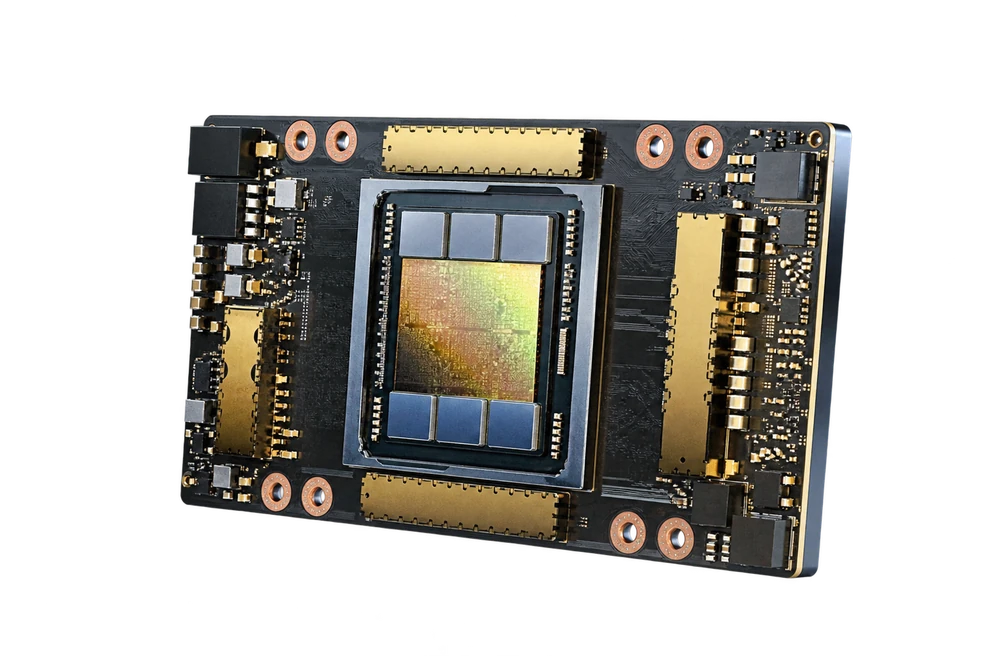
1 × GPU40 GB per GPU
GPU-A100 40G
New generation server with A100 40GB GPU
- CPU
- 2 x Intel Xeon Gold 6133
- RAM
- 128 GB
- Storage
- 2TB SSD NVMe
- GPU
- Nvidia A100 40GB
- Human processing
- Cuda Core - Tensor Core GPU
- IP
- 01 IPv4
- Support
- Contact Support to order
Save 15% when paying for 12 months Price maintains the service $1,600 / months - 15% when paying for 12 months
Order now 1 × GPU80 GB per GPU
GPU-A100 80G
New generation server with A100 80GB GPU
- CPU
- 2 x Intel Xeon Gold 6133
- RAM
- 128 GB
- Storage
- 2TB SSD NVMe
- GPU
- Nvidia A100 80GB
- Human processing
- Cuda Core - Tensor Core GPU
- IP
- 01 IPv4
- Support
- Contact Support to order
Save 15% when paying for 12 months Price maintains the service $3,200 / months - 15% when paying for 12 months
Order now 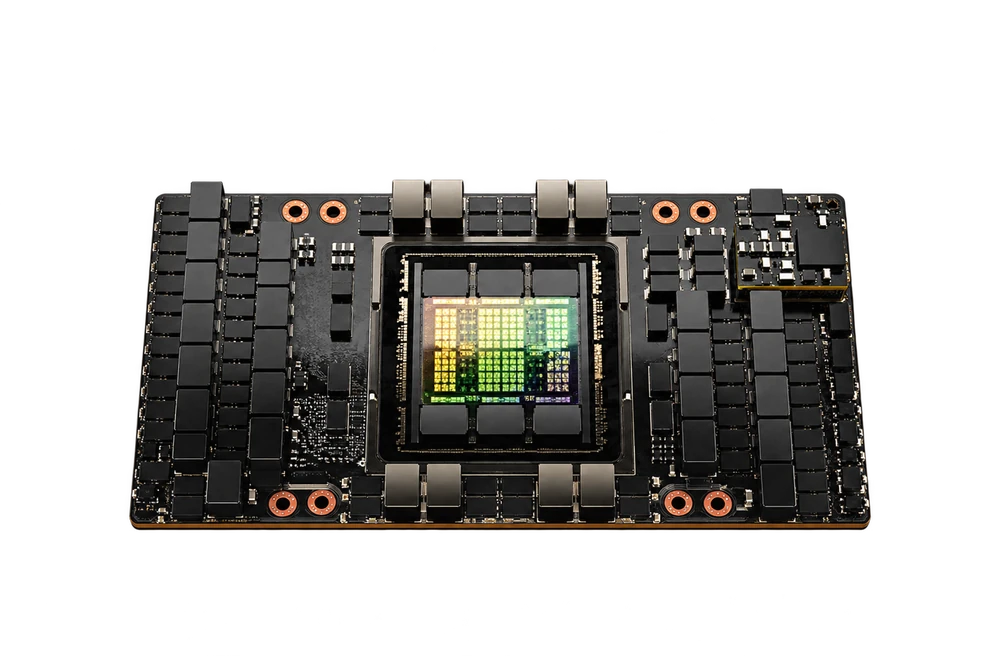
1 × GPU80 GB per GPU
GPU-H100 80G
New generation server with H100 80GB GPU
- CPU
- 2 x Intel Xeon Gold 6133
- RAM
- 128 GB
- Storage
- 2TB SSD NVMe
- GPU
- Nvidia H100 80GB
- Human processing
- Cuda Core - Tensor Core GPU
- IP
- 01 IPv4
- Support
- Contact Support to order
Save 15% when paying for 12 months Price maintains the service $3,800 / months - 15% when paying for 12 months
Order now